

Read time: 15 minutes
Three years ago, the use case method for figuring out what to build in data and AI was extremely popular.
Today, people are skipping it entirely because they think they can just build automatically with AI.
They aren’t wrong. But this perspective lacks a key point of why you go about building a use case in the first place.
And that is... drumroll please... to make sure the data or AI solution actually gets used by the right stakeholders!
Does that mean we should still take months to design use cases, get approvals, and figure out the components behind it? No, it doesn’t; with AI, we can deliver faster. But a key part of delivering faster still means getting buy-in so the end solution gets used.
This topic is important, especially right now. Building has never been cheaper. And alongside that, abandonment has never been higher. For example, in late 2025 the share of companies abandoning most of their AI initiatives before they reach production climbed from 17% to 42% year over year, with the average organization scrapping 46% of its proofs-of-concept. A big reason for that is improper scoping and a lack of buy-in!
That’s why this week we are going to explore building data and AI use cases in this world of embedded AI, specifically with scoping and buy-in top of mind. If you haven’t checked them out yet, take a look at my last three articles, which talked about the core DevOps, DataOps, AgenticOps, and Solutions Architecture principles for designing, building, and maintaining data and AI solutions.


Let’s start with the process, because that is where everything should start anyway!
Getting Buy-in Via The Use Case Process is Essential
I’ve built data & AI use cases dozens of times for a number of small, medium, and large organizations. Each time, it follows a similar pattern:
Talk to stakeholders and interview them about their challenges, needs, and what they want.
Figure out the feasibility and how those needs connect to potential data and AI solutions.
Scope out the dependencies, requirements, and a potential value for each.
Identify how that comes to be and what it would take to bring that idea to life; thinking holistically about all the use cases as one instead of each individual use case in a silo
This wasn’t a hard process. Companies just needed support to do it because they didn’t have the expertise, time, or capacity.
Now companies are deciding that this might not be something they want to outsource or spend existing resources and time doing; rather, they are just using AI to scope these things out and skipping the consultation process entirely.
As with a lot of things I write about, this is very short-term thinking. What you end up doing is accelerating the process to the point where business stakeholders have little to no input into the data and AI solutions they are supposed to use in the future. Therefore, you get rid of the opportunity for them to provide their perspectives and get overall buy-in to the plan/ direction of your data and AI program.
Or on the other side, maybe the business stakeholder is doing the whole scoping without the help of the data or technical team? In that scenario, the technical complexities and dependencies are completely ignored ensuring the use case is not feasible and never gets past POC stage.
Either approach diminishes the data culture, leads to unused solutions, and creates a growing chasm between the non-technical and technical teams. And AI is not positioned/ or capable of solving any of this, as an fyi.
So thinking back to the classic process, these are the three things I love about it and wouldn’t replace:
You bring the right questions to stakeholder – Requirements gathering is about asking questions that documents, systems, and technology can’t answer. And through those, you get to the heart of the issue/ opportunity. The responses that come from that—even if they might be obvious to the stakeholders—often go ignored by the data and technical teams
You get put in front of the right people – Silos are always the biggest problem, especially in large organizations. Going through a use case definition process creates an excuse for people to make time in their busy schedules to talk to you about what they need and want. Sometimes, at a busy organization, you need that excuse, especially with senior leaders
You accumulate buy-in – The most important part of all of this: buy-in. When you sit down, talk with, and empathize with the business stakeholders, they feel part of the process and get excited about the end result. This is what makes the solution get used after it is built.
I’m also here to tell you that this doesn’t need to change; and it also doesn’t need to take 2-3 months.
Still ask the questions. Book the meetings with the right stakeholders, use AI to generate the right list of questions. Use AI to synthesize and compile the key takeaways/ outputs from the interviews. Then go back to stakeholders and show them a working version of the redesigned process or scoped-out use case rather than having them forget about it a month later.
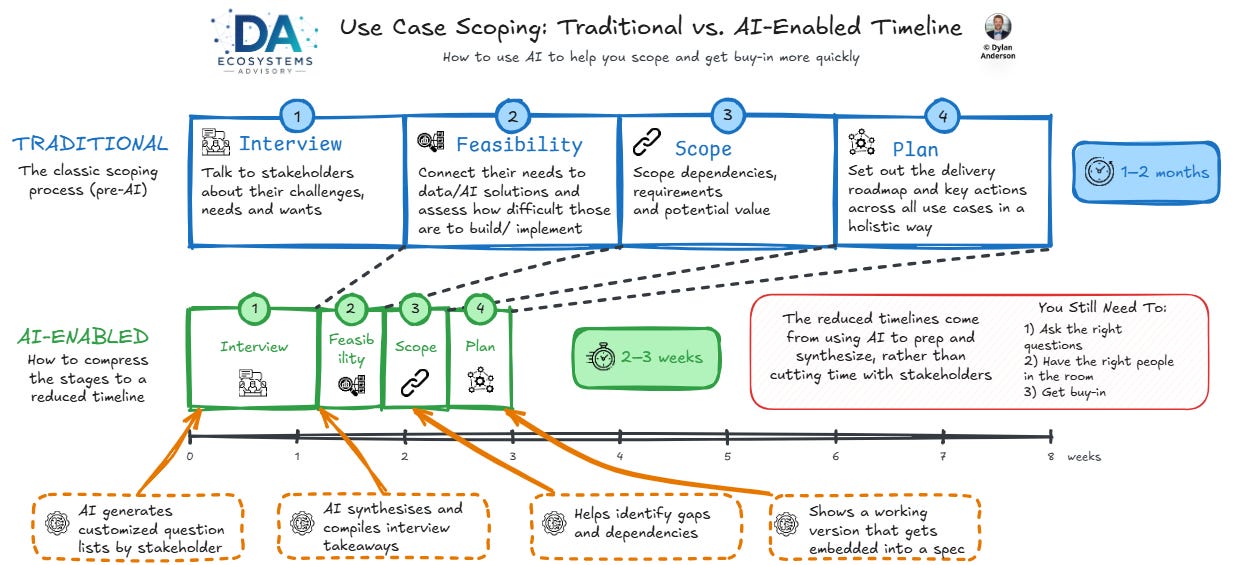
Honestly, this cuts the process from 2-3 months down to 2-3 weeks (depending on meeting availability and the number of stakeholders). AI really is a game changer, but you still need to follow the change management process to get buy-in and build the right use cases.
Now let’s get into some more practical elements of a well-designed use case (hopefully that process is practical as well)!
The Three Steps of a Well-Designed Use Case
AI isn’t here to speed up how we do things today. As I’ve written about, it is here to change how we work, enabling us to be more efficient and effective in the future.
That means not changing what works, but speeding up what doesn’t work. For scoping data & AI requirements, designing the products/ solutions, and building a culture around it, the things I mentioned above work!
So the point of AI, is not to skip these things (just like I talked about last week with Solutions Architecture), but to make it more efficient and effective.

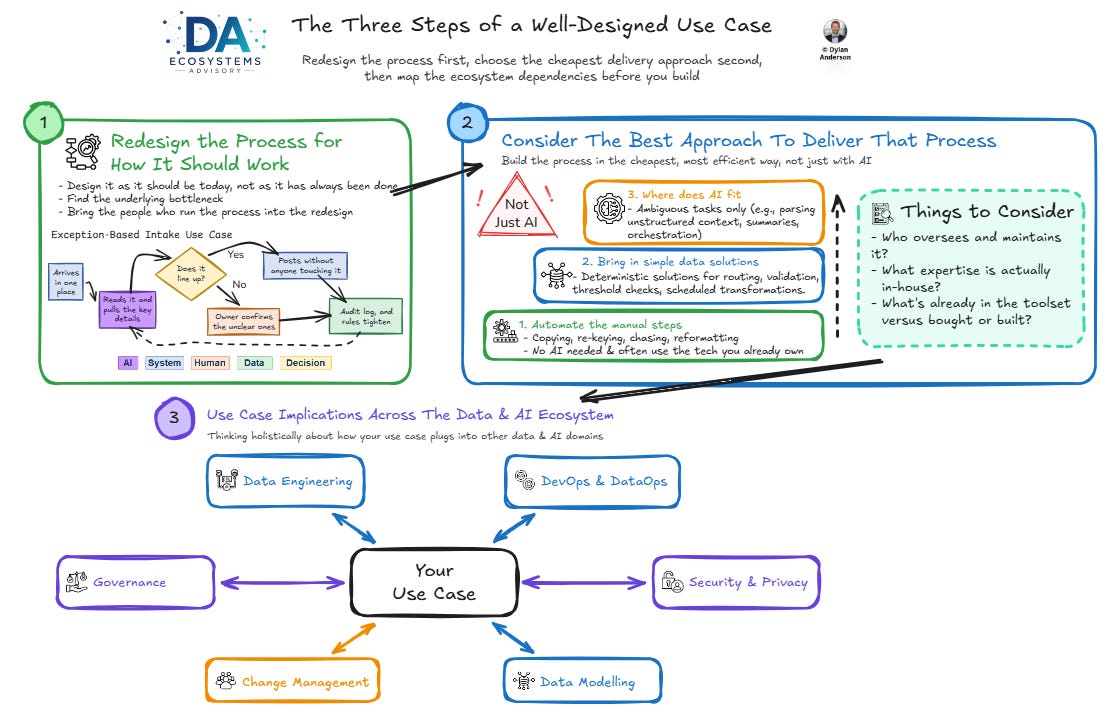
When I approach a data & AI use case, I therefore think about it in three steps, in this order:
Step 1 — Redesign the Process for How It Should Work
The biggest problem with most companies is that they work the way they do because that is how it’s always been done. And you know what, for a long time, that worked and it worked well. But now, things are changing—and data & AI is at the forefront of that. Therefore, the most common way a use case goes wrong is that somebody takes the process exactly as it exists today and points AI at it.
Instead think about how it should work if you were designing it today, with the tools that exist today.
The biggest problem is that when technology removes a limitation, the rules you built to accommodate that limitation don’t remove themselves. They stay, and then the rules become the limitation. For example, if you add an approval step because a report was manual, even if the report gets automated, the manual approval step often remains for years to come.
And nobody really has the guts to rip off the band-aids that used to hold these processes together.
The work in this step is to identify the underlying bottlenecks and redesign around them. A big part of this is bringing the people a part of the process into the redesign step rather than handing it to them finished because as I’ve mentioned before a process the team helped design has more buy-in than one they are handed (having been a consultant for a decade, this is one big thing that differentiates good vs. bad consultants).
Step 2 — Really Consider The Best Approach To Deliver That Process
This is where a lot of people get really lazy when they design data and AI use cases. And within that camp, I would 100% include strategy consultants because they have absolutely no idea what it takes to implement a technology or data solution; instead, they rely on buzzwords that sound nice but have no real meaning.
How you do this isn’t fun, it isn’t sexy, and it isn’t “let’s just use AI.” Honestly, that kind of approach is just plain lazy. Should we use AI? Yes. But use AI where it makes sense. Therefore, start with the cheapest way to deliver the process you just designed:
First, automate the manual steps – Start with the obvious stuff. Where in the redesigned process is somebody copying, re-keying, chasing or reformatting something? That work is usually the easiest to take out, and it delivers benefits immediately. It’s not hard either; automation can be done with tech you already own/ pay for, or with a simple data script. No AI needed…
Bring in simple data solutions – I’ve talked a lot about the deterministic layer, and by deterministic I mean the work where the same input always gives you the same output based on rules you set out. Routing, validation, threshold checks, scheduled transformations. Honestly, a big chunk of what people are currently asking AI to do should be done this way, and it would be cheaper and more reliable if it were
Finally, where does AI fit – Lastly, embed AI into the process. Here I focus on ambiguous tasks (like parsing context from unstructured data/ random templates or generating outputs like summaries). Also, using AI as an orchestration tool for non-data stakeholders is another good part of the design, especially with MCPs and agentic skills
It is worth noting that whatever lands in that third bucket is only as good as the data underneath it. If the source or system is a mess, you need to fix/ adjust that source before the AI part works.
The other thing to consider is what your organization can run and how they do it:
Who is overseeing and maintaining this? The team or person to run each point in the process
What is the actual level of expertise in-house? Making sure the owner can actually deliver what is needed or designing your process so that the people you have available can deliver against it. This may mean not opting for the most optimal process to make it practical
What’s already in the toolset versus what has to be bought or built? Start with what you’re already paying for, especially because most companies are barely scratching the surface of the potential for the licences/ tools they already pay for
This is often where companies overshoot. We design for what sounds good rather than what’s realistic, because what sounds good sells (and then it doesn’t deliver).
For example, I have had a few clients with an ERP or CRM that is nowhere near being used to its full abilities. Among the use cases we identified, we found that certain processes didn’t need a new tool or resource; their existing tools could meet those needs with a few weeks of tweaking and training.
Moreover, in one of these examples, they had a Microsoft ERP that had Copilot plugged in (but wasn’t being used), allowing them to use a paid-for AI tool to help them redesign and improve their process. That was a seriously easy recommendation and positive outcome!
Step 3 — Think Holistically About What That Means
With a redesigned process and a sensible view of how to deliver it, the other biggest thing is thinking about the dependencies.
I always like to frame this as thinking holistically, because as we know, a use case cannot be run independently and shouldn’t be built in a silo; instead, it plugs into the whole data & AI ecosystem.
Here are some elements you should think about within your use case (note you don’t have to solve for all of them, but considering them is important going into the build phase):
Governance – The market for data & AI governance experts is hot right now. The reason? Because organizations are thinking more and more about how to govern their data, tools and solutions to maintain quality, reliability and be compliant
Data Engineering – This one kind of goes without saying: you need data; it needs to be piped in; engineering will help with that
DevOps & DataOps – Think about how the use case gets built, released, versioned, monitored, and maintained with the right quality. Ever more important in this world of AI…
Security & Privacy – Personal data, access controls, external exposure, etc. Just like governance, SecOps and privacy are becoming more important, especially due to AI’s recent exploits
Data Modelling – As more use cases are built with AI plug-ins/ MCP connectors, how it draws context in the right way from the data (via a well-modelled foundation) will be increasingly essential. An ERD by use case isn’t the worst idea
Change Management – Of course I’m going to mention the organizational changes. Think about processes and people who will be involved/ impacted from the new use case
At this stage of the use case design, you have an opportunity that you don’t get again (or at least you don’t get very easily). That is the opportunity to plan correctly, making sure you consider any dependencies and through lines for the use case you want to deliver. If you don’t do that, something will fall through the cracks sooner rather than later.
Use Cases Via Specs
With AI, a lot of the use case process has stayed similar (maybe just been accelerated with better tools). But actually crafting a document to inform the use case build has evolved. In fact, this is probably the biggest change I have adopted into my use case process.
For me, it means creating a ‘spec’ document. The idea of a spec has been around for a long time, especially in the software world. But now with AI, it is possible to use spec design to create more data- and AI-focused solutions with business requirements/ inputs to bridge the business and technical gaps (especially after gathering the relevant information through the interview process mentioned earlier).
You could create your own spec, but I’ve used an open-source GitHub toolkit called Spec Kit. With this type of spec kit, even business or non-technical focused stakeholders should be starting to design the inputs that will feed a coding agent, and ensure what it puts out is correct. That helps you bridge the gap that has existed for so long between requirement gathering and the technical build.
Therefore, the spec helps you describe what and why, and doesn’t just skip to the how. This makes the spec completely approachable for non-technical stakeholders to confirm the output and/ or update as needed.
The biggest gap in that the Spec Kit skill I identified above is that it is still a bit technical and doesn’t include some of the business components you should probably have in a use case.
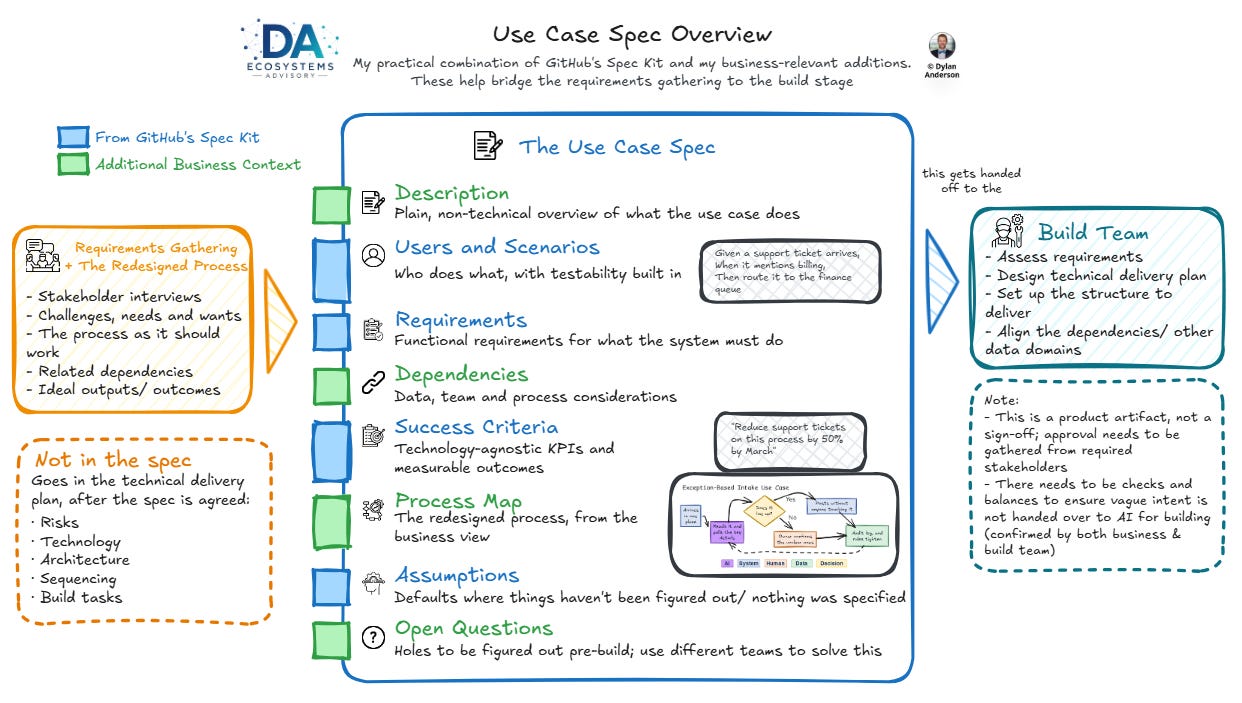
So I’ve added those in. Below, here is what you should have/ think about and where it comes from below:
Description (non-Spec Kit) – Provide an overview of what the use case does in basic, non-technical language
Users and Scenarios (Spec Kit skill) – Who does what, written as: Given this situation, when they do this, then this should happen. This provides specificity on how things should work with acceptance scenarios and testability built in
Requirements (Spec Kit skill) – Functional requirements for what the use case/ system must do
Dependencies (non-Spec Kit) – This builds on requirements but is an add-on I always make sure I include. The three components of this are data (what you need, here it is sources, who owns it, etc.), team (who needs to be involved), and process (what processes input or output from this use case)
Success Criteria (Spec Kit skill) – Technology-agnostic, measurable outcomes. An example of this might be “reduce support tickets on this process by 50% by March”
Process Map (non-Spec Kit) – Mapping out the redesigned process map you already created, helping identify what needs to happen from a business perspective so it isn’t forgotten by the technical design
Assumptions (Spec Kit skill) – Any default assumptions you built the spec with that hasn’t been specified. This helps you be more holistic when thinking about what could go wrong
Open Questions (non-Spec Kit) – What holes still exist that need to be figured out, so that if this spec is fed to an AI coding agent, it isn’t making things up and it reminds you to close the loop on things
By putting all this together, you have a spec that acts like a product artifact and provides a perfect AI-enabled bridge from the business-friendly requirements gathering/ process redesign to an output the build team can easily work with. You also create the checks and balances to ensure you are not handing vague intent to your dev team or an AI coding agent.
The two things I haven’t included in this are risks and technology components. These things can be identified in some of the areas above (e.g., requirements, assumptions, open questions, etc.), but should be tackled in the technical delivery plan. Other things that should be included in the technical delivery plan are the architecture, sequencing, and build tasks. These are all written after the spec is agreed, usually with a lot more technical input.
Using The Use Case Spec
I’ve used this approach for some client projects, but also for a lot of my own work. By doing this, I’ve built an analytics tool to measure and optimize my social media, a CRM to help me manage my networking/customer relationships, and am currently using this approach to design a knowledge graph that covers my writing, consulting materials, and best-practice internet research (all which help me write my newsletters and deliver client work).
A few tips I will share when I build the spec via Claude Code in VSCode are:
When I hit something I can’t answer, I mark it in the document: [NEEDS CLARIFICATION], so I don’t forget it and actually come back to it before pushing to the next step
The Spec Kit has a separate step that reads the spec back to you and asks a handful of targeted questions to close any questions
I specifically outline where I want to be consulted and where I need to approve to go to the next step
In typical DevOps fashion, I build in a modular way, making sure that my coding agent isn’t doing one huge task at once but breaking it down to the smaller pieces
The other bit I would add is that for teams building these things, you can use AI to close any open questions that exist. By marking it an open question and identifying the team/ individual owner, you can then use AI/ MCP to route that question to the right stakeholder via email, Slack, etc. The AI can use your spec to draft the specific communication each stakeholder needs, send it to them, collect the answer, and write it back into the spec. This reduces the project management requirements and the roadblocks to getting the right answer.
And you do the same thing with approvals. Every gate in the design and the delivery (e.g., the spec sign-off, the plan sign-off, the go-live decision, etc.) can be routed to the person who owns that gate via a channel/ medium they use.
By approaching your use cases with a spec kit and using AI where possible, you can accelerate the engagement/ buy-in requirements gathering phase, streamline the spec design and reduce the project management/ approval roadblocks. So in a fraction of the time, you are still following best practice, but in a redesigned AI-driven way.
Please steal this, and let me know how you improve on it as well!
Next Time We Explore Value-Driven Prioritization
The spec kit is great, and designing use cases in this way is much more efficient, but it’s still missing something, especially given that a lot of AI hype is not living up to the desired outcome.
Because a use case can be beautifully specified, properly redesigned, fully bought into by the team, and still be the wrong thing to spend time and money on.
This is where prioritization comes in! And while I’ve spoken about this before, especially in the data strategy series, my good friend and data and AI product expert Nick Zervoudis is going to break it down in a much better way next week.

In the meantime, try out this method: pick a use case you’re already planning, and try writing the spec, with the what and the why. Use the spec kit skill if it’s helpful as well (though it does take some time to get set up and use it properly, especially if you customize it as I did)!
And obviously I’m going to say this, but if you want a hand designing the process layer underneath one of these, that’s a conversation I’m having most weeks now. So feel free to reach out.
Have a great weekend and see you next Sunday!
Thanks for the read! Comment below and share the newsletter if you think it’s relevant! Feel free to also follow me on Substack, LinkedIn, and Medium, or reach out if you are looking for some top-notch freelance consulting input! See you amazing folks next week!